Vision-language-action (VLA) models have achieved impressive performance in quasi-static
manipulation, but struggle in dynamic manipulation tasks because they operate on a single
observation at inference time. We identify two representational failures that underlie this
limitation. The first is motion ambiguity, where a single observation does not include
scene dynamics and therefore cannot anticipate the future state of moving objects. The second
is state aliasing, where visually similar observations from different points in a task
require different actions. We show that these failures persist regardless of model scale and
inference latency, proving that the bottleneck is missing temporal context rather than model
capacity.
Based on this insight, we propose TEMPO, which augments a pretrained VLA with two
temporal inputs: a motion summary extracted from a frozen video foundation model to resolve
motion ambiguity and a compact proprioceptive history to resolve state aliasing. TEMPO requires
no modification to the backbone and adds minimal compute overhead at training or deployment.
Across four dynamic manipulation tasks, it improves Bottle Handover success from 44% to 74% and
is the only method that solves state aliasing. Probing and ablation studies confirm that each
temporal signal independently addresses its corresponding failure. We further release
TEMPO-Bench, a benchmark of over 50k annotated frames for evaluating motion-aware robot
perception in both regression and multiple-choice formats.
Dynamic Tasks 🐇 No Quasi-static-ness! 🐢
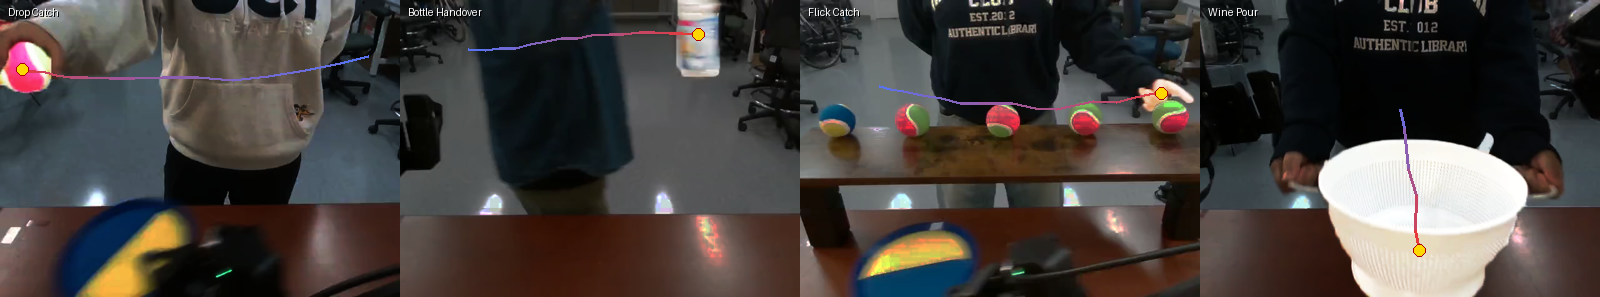
We evaluate on a bimanual platform across four dynamic tasks (Drop Catch, Bottle
Handover, Flick Catch, and Wine Pour), each with a moving target and sequential subtasks
that a single-frame observation cannot resolve. Every clip on this page is a rollout from
our trained TEMPO policy.
TEMPO Methodology
TEMPO adds two compact temporal signals to a frozen VLA, each fixing one failure mode with
near-zero overhead and no architectural change.
TEMPOMOT is an object-agnostic motion token from
a frozen video foundation model that summarizes how the scene is moving, fixing motion
ambiguity. TEMPOACT is a compact summary of the
robot's recent joint history that tells the policy which task phase it is in, fixing state
aliasing. Motion encoding runs in a background thread, so it adds essentially no inference-time
cost; we give the full architecture and a latency breakdown in the paper.
Results
Side-by-side rollouts of the same task: the asynchronous method
VLASH
versus TEMPO. VLASH cannot tell how the scene is moving or which phase of the task it
is in, so it mistimes the grasp or stalls entirely. TEMPO tracks the moving target and commits
at the right moment.
VLASH: Complete Miss
Success rate: 38%
VLASH
19
5
8
18
TEMPO (Ours): Catches
Success rate: 74%
TEMPO
37
3
10
SuccessNear CatchGripper MissComplete Miss
Receiving a bottle from a walking person. VLASH reaches for where the bottle was and
misses it entirely; TEMPO estimates the bottle's velocity and times the grasp to intercept it.
The bars beside each video break that method's 50 Bottle Handover rollouts into success (green)
and failure modes (reds); hover any segment for details.
VLASH: Misses the Catch
Success rate: 38%
VLASH
19
2
6
23
TEMPO (Ours): Catches
Success rate: 66%
TEMPO
33
4
7
6
SuccessLagged behind handOvershootPremature move
A ball is dropped into the workspace and the gripper has to be under it to make the
catch. Because VLASH cannot perceive how the ball is moving, it falls back on constantly
sweeping the gripper left and right even when the ball is still or barely drifting, so it
is rarely in the right place when the ball comes down; TEMPO reads the recent motion and
closely shadows the hand, staying under the ball through the drop. The bars beside each
video break that method's 50 Drop Catch rollouts into success (green) and failure modes
(reds); hover any segment for details.
VLASH: Fails to Track
Success rate: 20%
VLASH
10
3
37
TEMPO (Ours): Tracks & Catches
Success rate: 66%
TEMPO
33
4
9
4
SuccessFailed to Grab PlateFailed to Track HandFailed to Catch Ball
VLASH never picks up the object's motion, so its gripper fails to follow the ball and the
catch is missed. TEMPO learns the object-motion-to-action correspondence, tracks the appropriate
target, and catches it on time. The bars beside each video break that method's 50 Flick Catch
rollouts into success (green) and per-stage failures (reds); hover any segment for details.
VLASH: Spills More
Wine retained: 94.0%
TEMPO (Ours): Clean Pour
Wine retained: 98.1%
The robot pours beads into a pot the human keeps moving; success is the percentage of beads
retained in the pot. Both methods complete the pour, but VLASH lags the moving pot and spills
more, while TEMPO tracks the pot and pours cleanly.
State Aliasing: Stalls vs. Completes
VLASH: Aliased, Fails to Start
Success rate: 0%
TEMPO (Ours): Disambiguates, Succeeds
Success rate: 68%
The approach and retract phases of the gripper look nearly identical from a single frame. With
this state aliasing present in the demonstrations, VLASH collapses and cannot act; TEMPO's
proprioceptive history disambiguates the two phases, so the gripper approaches and retracts
normally and completes the task. See a deeper dive in
Why TEMPOACT helps? below.
TEMPO can complementarily use motion and proprioceptive information
We visualize the action expert's attention mass over a representative Flick Catch episode.
Attention on TEMPOMOT rises as the human hand starts
moving, corresponding to major movement in the observation, while
TEMPOACT steadily gains attention during the hand-
following phase and drops back down after the ball is caught. The two signals are consulted at
distinct moments: motion during tracking, proprioceptive history at commitment; the paper
develops this attention analysis in full.
Why TEMPOMOT helps? Its motion latent encodes object velocity that a single frame cannot reveal.
For each task we trace the active object's trajectory over the past 16 frames
(blue = 16 frames ago →
red = now;
yellow dot = current position). A probe then predicts
this motion from each model's aggregated hidden state; a higher R² means the representation
encodes object motion.
Method
Drop Catch
Bottle Handover
Flick Catch
Wine Pour
Avg.
RTC
0.31
0.46
-0.07
0.06
0.19
VLASH
0.28
0.43
0.03
0.09
0.21
TEMPO (Ours)
0.33
0.52
0.57
0.44
0.47
MLP probe R² over active object velocity. Where a single frame cannot reveal motion
(Flick Catch, Wine Pour), RTC and VLASH collapse toward zero while TEMPO stays high.
Why TEMPOACT helps? State Aliasing!
Why does a single-frame policy stall before it even starts? Because the same image recurs at
opposite moments of the task. In the real episodes below, the arm passes through the same configuration
once on the way in and once on the way out: the two highlighted frames are near-identical (their visual
similarity, measured by a frozen vision encoder, is shown in the middle) yet demand opposite actions.
Use the toggle to switch task.
≈
--
DINOv2 cosine similarity
play next 5s
Without proprioceptive history, VLASH oscillates and stalls.
The approach and retract phases of the gripper produce nearly
identical observations, so VLASH, conditioned on a single frame, cannot tell them apart and oscillates
between reaching and withdrawing, failing to even start the task. This is the artifact that
drives both RTC and VLASH to 0% on the state-aliased Flick Catch and Wine Pour tasks. TEMPO
completely resolves it: with a compact proprioceptive history, the policy knows which
phase it is in and the gripper approaches and retracts normally, as shown in the
state-aliasing success rollout above.
BibTeX
@misc{feng2026tempolearningtemporalcontext,
      title={TEMPO: Learning Temporal Context for Dynamic Robot Manipulation},
      author={Zhenyang Feng and Jimin Heo and Erik B. Sudderth and Unnat Jain},
      year={2026},
      eprint={2609.16864},
      archivePrefix={arXiv},
      primaryClass={cs.RO},
      url={https://arxiv.org/abs/2609.16864},
}